
TL;DR
- Choose a Scrape.do alternative around the output you need: fetched pages, structured records or a browser workflow.
- Compare feature costs and accepted records on the same source sample; a credit allowance is not a guaranteed page count.
- The Python example uses ScrapeGraphAI to extract a Books to Scrape product, check its fields and export JSON. It demonstrates one extraction workflow, not a vendor benchmark.

Run the example in Google Colab with your own ScrapeGraphAI API key.
Choose a Scrape.do alternative by the part of your workflow that needs to change. If you already have a reliable parser and need page access, compare fetch behavior. If maintaining the parser is the problem, compare structured extraction. If the job needs interaction or scheduled collection, include those requirements before comparing prices.
ScrapeGraphAI publishes this article. It compares documented capabilities, then provides one executed ScrapeGraphAI example. It does not rank the vendors by an unmeasured CAPTCHA success rate or promise that any tool can access every target.
Establish the current Scrape.do workload
Scrape.do's documentation includes a general web API, browser controls, asynchronous access and dedicated scraper products. Identify which of those products your existing pipeline uses before comparing its replacement.
Its pricing page lists Hobby at $29 per month for 250,000 successful API credits and Pro at $99 for 1.25 million. Credits are not automatically equivalent to pages with every option enabled. Inspect the request costs for your target and selected features.
Before changing providers, record the URLs, selected rendering and location options, returned format, parser behavior and accepted records from a representative run. A cheaper request that changes the response your parser expects can make the overall migration expensive.
Seven alternatives with different operating models
| Alternative | Documented capability to evaluate | Work you still need to check |
|---|---|---|
| ScrapeGraphAI | Schema-based extraction from URLs or supplied content | Source access, required-field correctness and credits |
| ScrapingBee | Page fetching, browser scenarios and extraction options | Selected parameters, output mapping and request cost |
| Bright Data | Access APIs and dedicated structured collectors | Exact product, record type and delivery model |
| Crawlbase | Crawling API with rendering and routing controls | Token type, target response and error handling |
| Oxylabs | Supported target sources and parsing options | Whether the chosen source returns the required fields |
| Apify | Packaged Actors and custom scheduled jobs | Actor-specific inputs, maintenance and billing |
| ZenRows | Fetch and extraction on a shared credit balance | Fetch settings, output contract and consumption |
ScrapeGraphAI when the desired output is a schema
Extract accepts a URL or supplied HTML or Markdown and a requested schema. This fits a migration that replaces a source-specific parser with an extraction step. The schema still needs application checks: a string called price can contain the wrong offer.
Start with one accessible target and compare the record with your existing parser. The example below shows that process on a public practice page. Plan consumption is documented on the pricing page; it should be mapped to accepted records rather than assumed to equal request count.
ScrapingBee when browser settings and parsing both matter
ScrapingBee documents browser scenarios, CSS/XPath extraction, AI extraction and dedicated scraper APIs. A migration can therefore preserve a selector-based parser or evaluate a different extraction mode without assuming all output must be raw HTML.
Inspect the exact request options and sample output. A plain fetch, a rendered interaction and a dedicated product lookup are different jobs. If your main comparison is with ScrapingBee, the separate ScrapingBee alternatives guide covers that tool-selection intent.
Bright Data when a packaged collector matches the target
Bright Data's scraper catalog contains predefined record types in addition to its access products. Compare the collector for your target, not a proxy-bandwidth price with a structured-record price.
A packaged collector can reduce mapping work if its record already matches your application. It can also introduce a fixed schema that needs adaptation. Inspect pagination, missing fields and whether delivery is synchronous or a batch result.
Crawlbase when replacing page retrieval
The Crawling API documents normal and JavaScript token paths, routing controls and browser behavior. It is a candidate for a pipeline that needs to retrieve page content and continue parsing it in your application.
Treat source status and provider status separately. Keep failure diagnostics and verify that the returned body is the intended page before feeding it into the parser. A request returning content is not sufficient if the content is a challenge or an empty shell.
Oxylabs when the target has a documented source
Oxylabs' supported-source catalog distinguishes raw formats and parsing availability. Check the entry for your actual target and operation, then inspect whether the output contains the fields needed downstream.
This matters when a general URL fetch and a target-specific search operation coexist. Compare the cost and result of the operation you will use, including parsing and location requirements.
Apify when the migration includes a job
Apify combines a platform with separately maintained Actors. An Actor may provide discovery, collection, storage and scheduling that your existing fetch call does not handle.
Evaluate the specific Actor, its input schema and current maintenance notes. Include its billing model and enabled resources in the forecast. A platform subscription alone does not establish the price or quality of an individual collector.
ZenRows when evaluating a shared fetch/extract model
ZenRows' pricing page describes a shared credit balance and states that Extract adds no cost beyond the Fetch request it uses. The fetch settings still determine consumption, so that statement should not be read as free page access.
Test the selected operation and the returned fields against your application's requirements. Keep the interface and response mapping explicit when migrating; similar operation names do not guarantee identical semantics.
A runnable migration check
This example extracts one product from Books to Scrape, a public demonstration site. It checks the product identity, converts the displayed GBP amount to integer pence and writes the accepted record. The source is intentionally simple; the result does not measure access to protected or heavily interactive sites.
Use Python 3.12 or newer. It makes one paid Extract request. Supply the key through SGAI_API_KEY or the hidden prompt. Run the cells in order.
import subprocess
import sys

if sys.version_info < (3, 12):
    raise RuntimeError("Use Python 3.12 or newer.")
subprocess.check_call([
    sys.executable, "-m", "pip", "install", "--quiet",
    "scrapegraph-py==2.3.1", "jsonschema==4.26.0",
])
The application contract requires a title, UPC and a decimal amount expressed in GBP. It does not accept a guessed amount or a different product with a similarly shaped record.
import os
from getpass import getpass
from decimal import Decimal
from scrapegraph_py import ScrapeGraphAI, FetchConfig
from jsonschema import validate

schema = {
    "type": "object",
    "properties": {
        "title": {"type": "string", "minLength": 1},
        "upc": {"type": "string", "minLength": 1},
        "amount_gbp": {"type": "string", "pattern": r"^\d+\.\d{2}$"},
    },
    "required": ["title", "upc", "amount_gbp"],
    "additionalProperties": False,
}
url = "https://books.toscrape.com/catalogue/a-light-in-the-attic_1000/index.html"
client = ScrapeGraphAI(
    api_key=os.environ.get("SGAI_API_KEY") or getpass("ScrapeGraphAI API key: ")
)
result = client.extract(
    "Extract the main book title, UPC and price excluding tax in GBP. "
    "For amount_gbp return only the decimal amount with two decimal places. "
    "Use the product information table and do not select a recommended book.",
    url=url, schema=schema, fetch_config=FetchConfig(mode="fast"),
)
if result.status != "success" or result.data is None:
    raise RuntimeError(f"Extraction failed: {result.error}")
data = result.data.json_data
validate(instance=data, schema=schema)
assert data["title"] == "A Light in the Attic", data
assert data["upc"] == "a897fe39b1053632", data
amount_minor = int(Decimal(data["amount_gbp"]) * 100)
assert amount_minor == 5177, data
The exact assertions refer to the reviewed demonstration page. If that page changes, inspect the source before changing the expected values. Do not automatically accept a new amount just because the extraction returned it.
import json
from pathlib import Path
from datetime import datetime, timezone

record = {
    "product_id": data["upc"],
    "title": data["title"],
    "amount_minor": amount_minor,
    "currency": "GBP",
    "source_url": url,
    "observed_at": datetime.now(timezone.utc).isoformat(),
}
path = Path("migration-pilot-record.json")
path.write_text(json.dumps(record, indent=2), encoding="utf-8")
assert json.loads(path.read_text(encoding="utf-8")) == record
assert isinstance(record["amount_minor"], int)
print(json.dumps(record, indent=2))
client.close()
A successful run writes migration-pilot-record.json with product ID a897fe39b1053632, title A Light in the Attic, amount 5177 and currency GBP, plus the source URL and observation time. This checks one live extraction and the stored record. It is not a performance comparison with Scrape.do or a test of every ecommerce site.
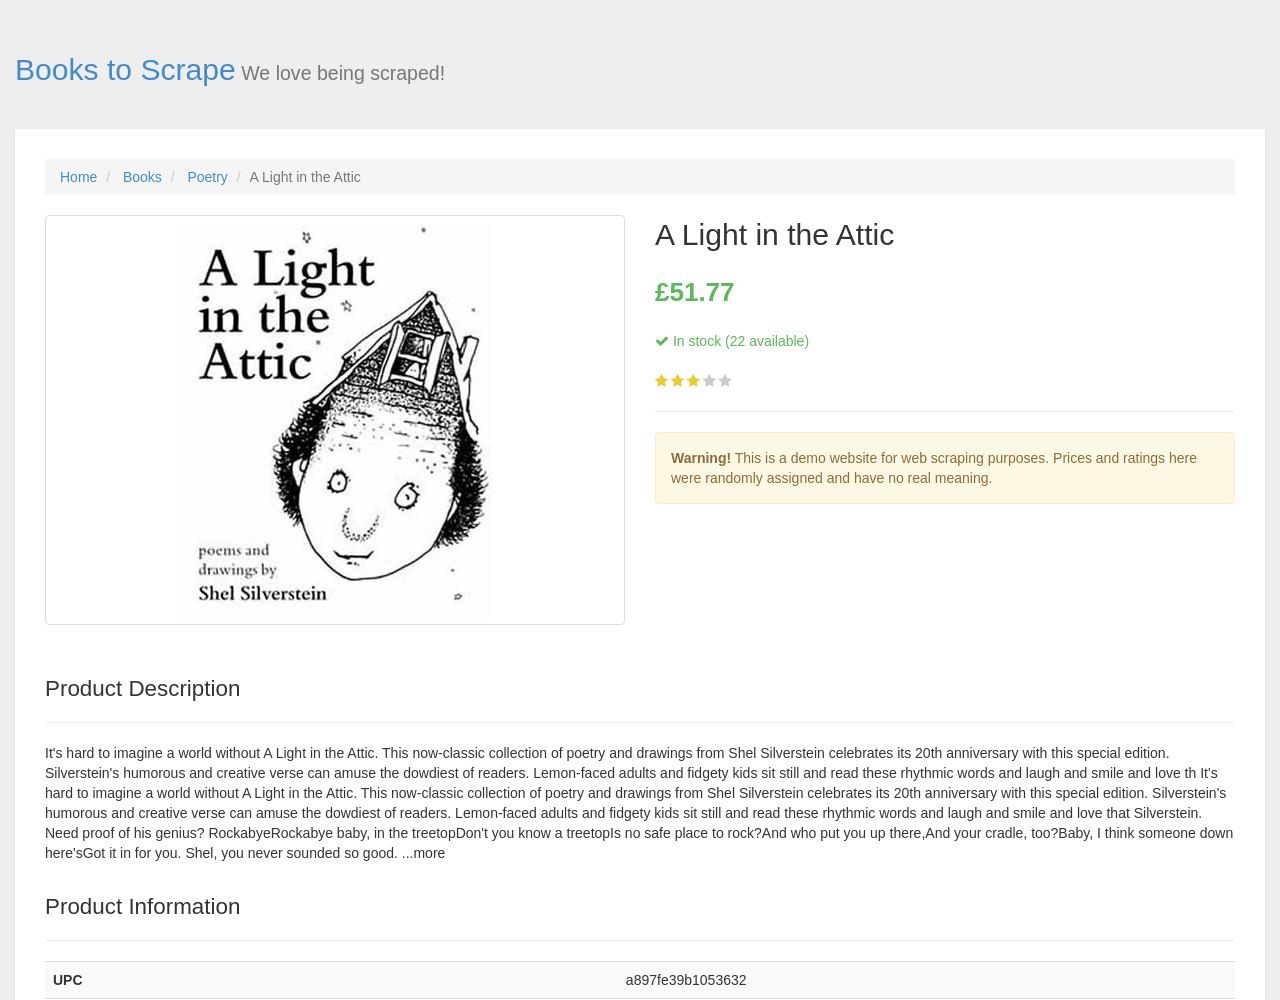
Books to Scrape. The displayed values are demonstration data.
Move a small workload before the whole pipeline
Apply the same acceptance checks to your existing collector and the candidate on representative inputs. Keep the record schema stable so the database and downstream reports do not need to change at the same time as the collection provider.
Measure accepted records, failed inputs, incorrect fields, latency and actual consumption. Include retries and any extra discovery or rendering work. For a provider comparison, repeat the same inputs under the same geographic and timing conditions and state the sample size.
Move a limited set of targets only after the candidate meets the agreed output requirements. Keep a way to switch that set back while reviewing the first scheduled runs. Use the economics calculator to include the integration and review hours in the migration cost, then update the forecast from actual usage.