


TL;DR
- Publicly visible data is not automatically unrestricted. The legal assessment depends on jurisdiction, access method, content and intended use.
- Review access restrictions, contracts, intellectual property and personal-data obligations separately.
- Describe the actual collection workflow before seeking advice. This guide explains selected US and EU issues; it does not approve a particular scraper.
Web scraping can be lawful, but a page being publicly visible does not settle every legal question. The answer depends on the jurisdiction, how you obtain access, what you collect, which terms apply, and how you use or share the result.
For a real project, separate access, contractual restrictions, intellectual property, and personal-data processing. Permission or an exception in one area does not automatically resolve the others. This guide explains selected US and EU issues using primary sources. It is general information, not a legal opinion on a particular scraper.
Start with the collection you actually plan to run
“Scrape a website” is too vague for a useful review. Describe the source URLs, fields, frequency, access method, storage period, and recipients. A daily collection of product prices for internal comparison raises different questions from republishing photographs or building profiles about identifiable people.
| Question | Evidence to collect |
|---|---|
| Who controls the source? | Publisher identity and applicable jurisdiction |
| How will the collector access it? | Public page, licensed API, login, export, or written permission |
| Which rules govern access and reuse? | Dated terms, license, API policy, or agreement |
| What will be retained? | Exact fields, source excerpts, images, and identifiers |
| Why is each field needed? | Specific business or research purpose |
| Who will receive it? | Internal users, customers, vendors, or public visitors |
| When will it be deleted or refreshed? | Retention period, deletion process, and schedule |
An official API or licensed dataset can make the permitted use clearer. It still has terms. Check whether the license covers your intended storage, redistribution, commercial use, and use by downstream services.
US computer-access cases do not create blanket permission
In Van Buren v. United States (2021), the US Supreme Court interpreted the CFAA's “exceeds authorized access” provision. It distinguished obtaining information from computer areas that are off limits from an improper use of information a person is otherwise entitled to access. The case concerned a police database, not a general license to scrape websites. Supreme Court opinion
The Ninth Circuit's April 2022 hiQ Labs v. LinkedIn opinion addressed publicly available LinkedIn profile information in the context of a preliminary injunction. Its discussion of CFAA access is often cited in scraping debates. It did not decide that every collection method, contract, or subsequent use of that information is lawful. Read the procedural posture and the limits of the issues decided before treating the case as permission for a different project. Ninth Circuit opinion
If a target requires credentials, restricts particular account areas, sends a cease-and-desist notice, or challenges the collector's access, stop treating the problem as merely a retry or proxy configuration issue. Have the proposed access method reviewed in the relevant jurisdiction. This is especially important before changing methods to continue a disputed collection.
Terms of service are a separate part of the review
A website may prohibit automated collection in its terms even when a visitor can load some pages without logging in. Whether and how those terms bind a particular collector depends on the facts and applicable law; a statement in a scraping tutorial cannot decide that question for you.
For example, LinkedIn's User Agreement includes restrictions on scraping and automated access. A third-party tool being able to retrieve a page does not establish that your proposed use satisfies the platform's agreement.
Keep a dated copy of the terms or license you relied on and document any written permission. If you use a data vendor, ask which rights it can grant you and what happens when a source withdraws access. A vendor's broad “compliant data” description is less useful than the actual contract and documented collection method.
Public personal data still needs a privacy analysis
Where the GDPR applies, a controller needs an appropriate legal basis for processing personal data. Consent is one possible basis; it is not the only one. Legitimate interests also has conditions and requires assessing the interests and rights of the people affected. Sensitive categories have additional conditions. Public availability alone is not one of the legal bases. European Data Protection Board guidance
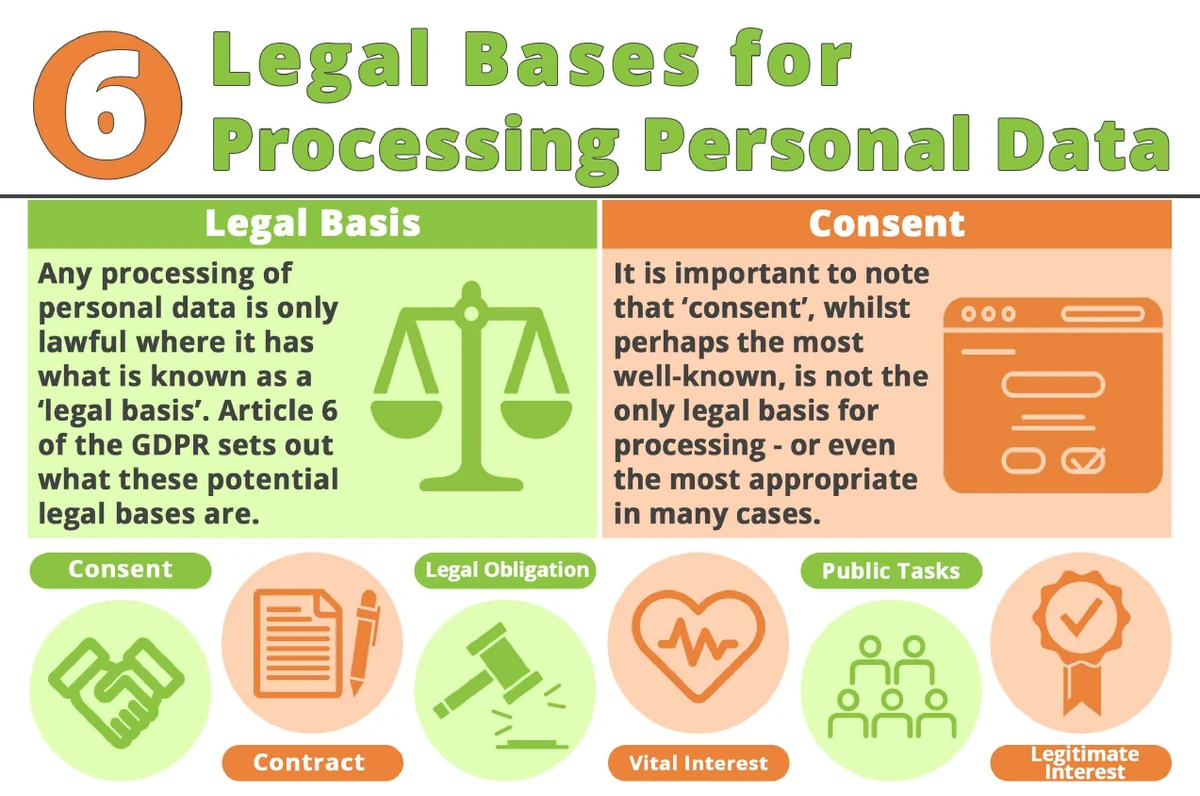 The six legal bases under GDPR Article 6. Excerpt from the Irish Data Protection Commission’s infographic.
Before collecting a name, personal email address, profile, or location history, identify why it is necessary. Consider whether organization-level information or aggregate statistics would answer the question with less personal data. Avoid adding fields simply because the extractor can find them.
Your review should also address transparency, retention, access controls, recipients, and how people can exercise applicable rights. A person's public post is not, by itself, permission to put them in a sales database or infer a sensitive characteristic about them. The lawful basis and the intended use need to be assessed together.
Facts, authored content, and databases are different
In the US, copyright does not protect facts themselves, but it can protect original expression, including website text and photographs. Collecting a displayed price and republishing a product photograph are therefore different acts to evaluate. A source link does not substitute for permission to copy protected content. US Copyright Office
EU database protection can also apply to qualifying collections. The EU's official business guidance explains that a database maker may have rights against extraction or reuse of all or a substantial part of its contents. Assess the database and the proposed extraction rather than assuming that unprotected individual facts make bulk reuse unrestricted. Your Europe: database protection
Text-and-data-mining exceptions, fair use, research exceptions, and licenses have jurisdiction-specific conditions. “For AI,” “for research,” or “for internal use” is not enough detail to establish that an exception applies. If the output republishes substantial text, images, or a competing database, bring that intended output into the review as well as the collection step.
Robots.txt is a crawler instruction, not a license
The Robots Exclusion Protocol lets services communicate crawling preferences. RFC 9309 explicitly distinguishes those rules from access authorization. A permissive robots file does not grant copyright rights, satisfy privacy obligations, or override a contract. RFC 9309
Respect the source's published crawling rules and collection limits. Identify your crawler where appropriate, avoid unnecessary repeated fetches, and stop or slow down when the service signals a problem. Those are useful operating practices, but they do not independently certify that a collection is lawful.
Give the collector an approved scope
Record the approved sources, access methods, fields, purpose, and retention period in a form the engineering team can implement. Give the collector an allowlist rather than unrestricted access to every URL returned by a model. Keep credentials out of notebooks and application logs.
Define what happens when a source changes its terms, an individual requests deletion, an API permission expires, or the collector receives an access objection. A scheduled job should have an owner who can stop it and trace where its records were sent.
For example, an approved supplier-monitoring job might retain product identifier, price, currency, source URL, and observation time. Adding reviewer names, profile photos, and personal contact details would expand that job's scope. Review that expansion before treating it as an ordinary schema change.
Frequently asked questions
Is scraping public data always legal? No. Public visibility is relevant to access, but contracts, privacy, intellectual property, and the intended use can still matter.
Do I always need consent? Not every collection concerns personal data, and consent is not the only possible basis under the GDPR. The applicable law and purpose determine what is required; do not assume a public page supplies consent.
Does using ScrapeGraphAI make a scraper compliant? No. A collection tool does not grant source permissions or decide your legal basis. Review the workflow you configure and the data you retain.
Can I scrape behind a login? A valid account does not settle whether automated collection or the proposed reuse is permitted. Check the scope of access, agreement, and applicable law before implementing it.
Does reducing the request rate solve the legal issue? It can reduce load on the source. It does not resolve licensing, personal-data use, or disputed access.
For platform-specific collection questions, see Instagram scrapers and public-data limits. For public health sources and the limits of automated de-identification checks, see healthcare data extraction.