


TL;DR
- This tutorial extracts document metadata from a public HHS guidance page, validates the result and saves its source URL and collection time.
- It does not process patient records or determine whether data meets de-identification requirements.
- Public reference material and patient information need different workflows. Choose the source, permitted use and required fields before sending content to an extraction service.

Run the example in Google Colab with your own ScrapeGraphAI API key.
Healthcare data extraction covers very different jobs. Cataloging public guidance documents is not the same as processing patient records. Choosing the source and deciding which fields you need should happen before sending anything to an external extraction service.
This tutorial builds a small catalog entry for a public HHS guidance page. It extracts document metadata, validates the fields, and saves the source URL and observation time. It does not process patient information or determine whether a dataset is de-identified.
Separate public references from patient information
| Source type | Example | Suitable starting point |
|---|---|---|
| Public guidance | Agency policy or reference page | Review reuse terms; extract document metadata |
| Public study registry | Trial identifier, status, and sponsor | Prefer the registry's structured API |
| Published research | Citation, abstract, or licensed full text | Use the permitted API or licensed material |
| Patient-level records | Clinical notes, laboratory results, bills | Establish the required agreements and controls before processing |
| Public patient discussion | A post describing an identifiable person's health | Assess personal-data purpose and sensitivity; visibility is not permission |
The word “healthcare” does not tell you which rules apply to a record. HHS explains that HIPAA protections concern individually identifiable health information held or transmitted by covered entities and their business associates. A public medical reference document and an identifiable patient's chart are different data categories. HHS de-identification guidance
For an internal clinical project, identify the data owner, approved processors, permitted purpose, access controls, retention period, and incident process before moving data. A tutorial API key is not approval to upload a clinical note. This article makes no claim that a particular ScrapeGraphAI plan or default configuration is appropriate for protected health information.
Why a few regex checks cannot establish de-identification
HHS describes two HIPAA de-identification methods: Expert Determination and Safe Harbor. Safe Harbor includes specified identifier categories and the condition concerning actual knowledge of remaining identifiability. Searching for a few email, phone, or identifier patterns does not satisfy that process. Free text and combinations of attributes can identify someone even when familiar patterns are absent. HHS guidance on the methods
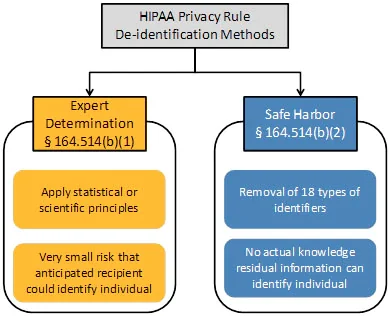 The two HIPAA de-identification methods and their core conditions. Source: HHS, Figure 1.
Use pattern detection as a limited screening tool if your approved workflow calls for it. Its output should mean “these patterns were or were not found,” not “safe to store” or “HIPAA compliant.” Also consider when screening occurs: detecting sensitive content after it has already been sent to an external service does not undo that disclosure.
A bounded public-document example
Our source is the HHS guidance linked above. The output contains only its title, publisher, and displayed review date, plus provenance added by our application. We chose and inspected this public reference page for this exercise. The script does not search for patient records or decide which other sites are appropriate to collect.
Use Python 3.12 or newer. This example makes one paid extraction request using your ScrapeGraphAI credits. The key is entered with a hidden prompt or read from SGAI_API_KEY.
import subprocess
import sys

if sys.version_info < (3, 12):
    raise RuntimeError("Use Python 3.12 or newer.")
subprocess.check_call([
    sys.executable, "-m", "pip", "install", "--quiet",
    "scrapegraph-py==2.3.1", "jsonschema==4.26.0",
])Restrict the source and output fields
An exact URL allowlist restricts the function to the selected source. It is a guard against accidentally passing a different URL to this function, not a general privacy classifier or a complete network-security control. Production systems also need to control redirects, credentials, and the collection destinations supported by their infrastructure.
import os
from getpass import getpass
from scrapegraph_py import ScrapeGraphAI, FetchConfig
from jsonschema import validate

source_url = "https://www.hhs.gov/hipaa/for-professionals/special-topics/de-identification/index.html"
allowed_urls = {source_url}
schema = {
    "type": "object",
    "properties": {
        "title": {"type": "string", "minLength": 1},
        "publisher": {"type": ["string", "null"]},
        "updated_date_text": {"type": ["string", "null"]},
    },
    "required": ["title", "publisher", "updated_date_text"],
    "additionalProperties": False,
}
client = ScrapeGraphAI(api_key=os.environ.get("SGAI_API_KEY") or getpass("ScrapeGraphAI API key: "))

def reference_metadata(url):
    if url not in allowed_urls:
        raise ValueError("This exercise accepts only its reviewed public HHS source.")
    response = client.extract(
        "Extract the main title, publishing organization, and article-specific "
        "last reviewed or updated date exactly as shown. Ignore navigation, "
        "copyright years and footer dates. Return null when a publisher or "
        "article date is not stated.",
        url=url, schema=schema, fetch_config=FetchConfig(mode="fast"),
    )
    if response.status != "success" or response.data is None:
        raise RuntimeError(f"Extraction failed: {response.error}")
    data = response.data.json_data
    validate(instance=data, schema=schema)
    return data

metadata = reference_metadata(source_url)
assert "De-identification" in metadata["title"], metadata
assert metadata["updated_date_text"] == "February 3, 2025", metadata
print(metadata)
The assertion checks the source's review date, “February 3, 2025.” If HHS updates the page, inspect the displayed date and update the expected value. Do not use the notebook's run date as the document's review date.
The Extract documentation describes the request interface. Successful extraction means a response was produced; the local schema and assertions then check the record we intend to retain.
Save a source catalog entry
The application supplies the URL and collection time. Asking a model to invent those fields would make provenance less reliable. The collection_scope value records the exercise's predefined purpose; it is not a compliance verdict generated from the page.
import json
from datetime import datetime, timezone
from pathlib import Path

record = {
    "source_url": source_url,
    "observed_at": datetime.now(timezone.utc).isoformat(),
    "collection_scope": "public-reference-document-metadata",
    "metadata": metadata,
}
output_path = Path("healthcare-reference.json")
output_path.write_text(json.dumps(record, indent=2, ensure_ascii=False), encoding="utf-8")
assert json.loads(output_path.read_text(encoding="utf-8")) == record

try:
    reference_metadata("https://portal.example.invalid/patients")
except ValueError:
    print("Rejected an unapproved URL before making a request")
else:
    raise AssertionError("The URL allowlist did not reject the test input.")

print(f"Saved document metadata to {output_path}")
This example tests a real public source, a file round trip, and rejection of an unapproved input before network access. It does not test clinical interpretation, patient-data handling, or a de-identification method.
Choose structured sources when they already provide the fields
For trial identifiers, recruitment status, and registry dates, use the ClinicalTrials.gov API. The clinical data extraction guide explains how to retain source-specific identifiers and avoid treating unrelated registry, publication, and adverse-event records as interchangeable observations.
For literature, inspect the publisher's permitted access route and the difference between citation metadata and full-text rights. For adverse-event sources, preserve the source's limitations: a reported event is not automatically evidence that a product caused it. The openFDA documentation explains why those reports cannot by themselves establish causation or incidence.
Review the workflow when its purpose changes
A catalog of public reference documents does not authorize adding patient notes to the same job. Reassess the fields, processors, storage, and permissions when the source or use changes. Keep that decision with the workflow's owner rather than delegating it to a prompt that labels content “safe.”
Use the web scraping legal guide to organize the access and reuse questions. For operational verification, retain a small reviewed sample and track retrieval failures, missing metadata, and changed dates separately.