
TL;DR
Measure web scraping cost per accepted record: the data that meets your field, quality and freshness requirements. Include retries, validation and maintenance in that cost. AI extraction earns its place when the resulting workflow delivers useful data at a budget you can defend.
This guide uses an illustrative monthly budget and a runnable calculator. The numbers are assumptions you can replace, not customer results or an industry benchmark.

Run the calculator in Google Colab with your own cost assumptions. No API key is needed.
Define a usable record
A request that returns HTTP 200 can still return the wrong price or an empty list. Before comparing costs, decide what counts as success. For a product-monitoring job, you might require the product identifier, price, currency, seller, source URL and collection time. A record must meet your freshness requirement and pass field checks before it counts toward delivery.
Keep attempts, returned records and accepted records separate. A page can contain several products, and a product can require several requests. Mixing pages, requests and records makes a per-unit comparison misleading.
Inventory the costs you already pay
Start with the last complete billing period. Separate costs that change with volume from costs you pay even when the job is idle.
| Cost | What to record | Evidence to use |
|---|---|---|
| Page access | Proxy bandwidth, browser runtime, API requests and retries | Provider invoices and request history |
| Extraction | Parser runtime or model usage | Runtime metrics and model bills |
| Engineering | Initial integration and recurring maintenance hours | Work logs, incidents and change history |
| Validation | Human review and automated checks | Review samples and rejected records |
| Storage and delivery | Files, database operations and exports | Storage and infrastructure invoices |
Count each hour once. If an engineer's monthly allocation already includes maintenance, adding the same maintenance hours again inflates the baseline. Initial setup belongs in the migration budget, not in every recurring month.
Also distinguish cash savings from capacity. Moving an existing engineer to product work can be useful without reducing payroll. Present those outcomes separately when asking for budget.
A monthly comparison you can inspect
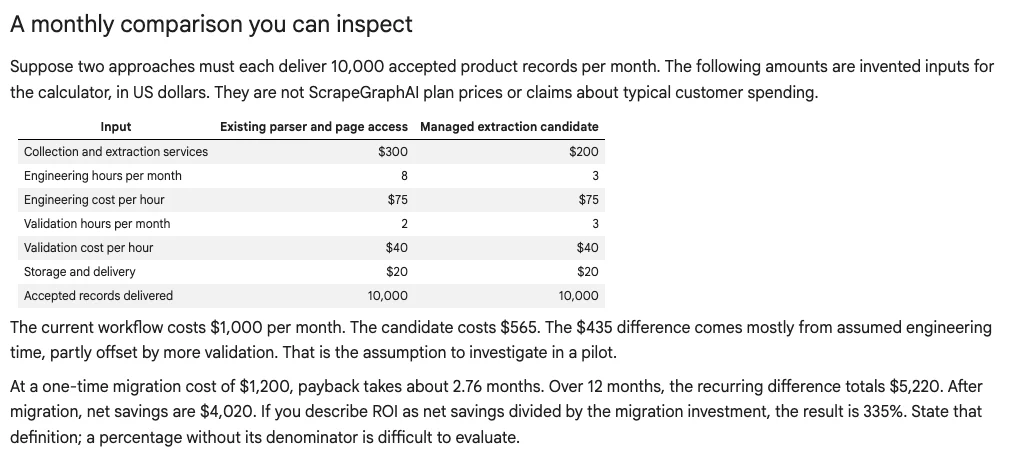
Suppose two approaches must each deliver 10,000 accepted product records per month. The following amounts are invented inputs for the calculator, in US dollars. They are not ScrapeGraphAI plan prices or claims about typical customer spending.
| Input | Existing parser and page access | Managed extraction candidate |
|---|---|---|
| Collection and extraction services | $300 | $200 |
| Engineering hours per month | 8 | 3 |
| Engineering cost per hour | $75 | $75 |
| Validation hours per month | 2 | 3 |
| Validation cost per hour | $40 | $40 |
| Storage and delivery | $20 | $20 |
| Accepted records delivered | 10,000 | 10,000 |
The current workflow costs $1,000 per month. The candidate costs $565. The $435 difference comes mostly from assumed engineering time, partly offset by more validation. That is the assumption to investigate in a pilot.
At a one-time migration cost of $1,200, payback takes about 2.76 months. Over 12 months, the recurring difference totals $5,220. After migration, net savings are $4,020. If you describe ROI as net savings divided by the migration investment, the result is 335%. State that definition; a percentage without its denominator is difficult to evaluate.
Run the calculator
The code uses Python's standard library. It needs no API key and makes no network requests. Change the inputs to match your own records, then run the cells in order.
 The Colab calculator uses illustrative inputs for the same accepted-record target. Replace them with your own costs.
from dataclasses import dataclass


@dataclass(frozen=True)
class MonthlyCost:
    services: float
    engineering_hours: float
    engineering_hourly_cost: float
    validation_hours: float
    validation_hourly_cost: float
    storage: float
    accepted_records: int

    def total(self):
        values = (
            self.services,
            self.engineering_hours,
            self.engineering_hourly_cost,
            self.validation_hours,
            self.validation_hourly_cost,
            self.storage,
        )
        if any(value < 0 for value in values):
            raise ValueError("Costs and hours must be nonnegative")
        if self.accepted_records <= 0:
            raise ValueError("Accepted records must be positive")
        return (
            self.services
            + self.engineering_hours * self.engineering_hourly_cost
            + self.validation_hours * self.validation_hourly_cost
            + self.storage
        )

    def per_record(self):
        return self.total() / self.accepted_records


current = MonthlyCost(300, 8, 75, 2, 40, 20, 10_000)
candidate = MonthlyCost(200, 3, 75, 3, 40, 20, 10_000)
migration_cost = 1_200
months = 12

if current.accepted_records != candidate.accepted_records:
    raise ValueError("Compare workflows delivering the same number of records")
if migration_cost <= 0 or months <= 0:
    raise ValueError("Migration cost and comparison months must be positive")

monthly_savings = current.total() - candidate.total()
net_savings = monthly_savings * months - migration_cost
roi = net_savings / migration_cost
payback = migration_cost / monthly_savings if monthly_savings > 0 else None

print(f"Current monthly cost: ${current.total():,.2f}")
print(f"Candidate monthly cost: ${candidate.total():,.2f}")
print(f"Current cost per accepted record: ${current.per_record():.4f}")
print(f"Candidate cost per accepted record: ${candidate.per_record():.4f}")
print(f"Monthly savings: ${monthly_savings:,.2f}")
print(f"Net savings over {months} months: ${net_savings:,.2f}")
print(f"ROI on migration investment: {roi:.1%}")
if payback is None:
    print("No payback from recurring cost savings")
else:
print(f"Payback: {payback:.2f} months")Expected output for those inputs:
Current monthly cost: $1,000.00
Candidate monthly cost: $565.00
Current cost per accepted record: $0.1000
Candidate cost per accepted record: $0.0565
Monthly savings: $435.00
Net savings over 12 months: $4,020.00
ROI on migration investment: 335.0%
Payback: 2.76 months
Check what would reverse the decision
A single estimate hides uncertainty. Keep the same target output and vary the candidate's engineering hours. This cell reuses the objects from the previous cell.
from dataclasses import replace

for hours in (3, 6, 9):
    scenario = replace(candidate, engineering_hours=hours)
    savings = current.total() - scenario.total()
    print(
        f"{hours} engineering hours: "
        f"${scenario.total():,.2f}/month, "
        f"${savings:,.2f} monthly savings"
    )
The resulting candidate budgets are $565, $790 and $1,015. At nine engineering hours, it costs $15 more per month than the current workflow and the migration has no payback from recurring savings. A change in one assumption reverses the result.
You can use the same approach for retry rates, validation time or the percentage of records rejected. If accepted output drops, increase collection volume and the associated costs until both workflows meet the same requirement. Comparing a complete delivery with a cheaper partial delivery is not a useful savings estimate.
Put provider billing into the model
Map the provider's unit to the workflow before filling in the services column. Bandwidth, records, credits and browser time describe different things. Include the cost of retries according to the provider's actual billing rules.
For ScrapeGraphAI, the pricing page separates plan allowances from endpoint costs. An extract has a five-credit base cost; enabling stealth adds five credits. A credit allowance therefore is not an equal number of extractions. Use the price calculator to inspect the selected operation, then reconcile it with your own usage history. Check the current plan before budgeting: the free allowance and subscription credits have different renewal rules.
The services figure in the example is a hypothetical budget. Replace it with a plan that covers your measured usage and any required top-ups. Do not multiply a discounted high-volume unit price by a small workload unless that price is actually available to you.
Design a pilot that produces a decision
Choose a small set of targets representative of the job: the layouts that are easy, the ones that currently fail, and the ones with the most expensive validation. Record the URLs, requested fields, run dates and settings so someone else can repeat the comparison.
Use the same acceptance rules for both workflows. Manually verify a sample of returned fields against the source and record why rejected records failed. Track elapsed time and operational effort as well as the bill. One successful request demonstrates that one request worked; it does not measure an ongoing success rate.
For a price-monitoring workflow, compare the same seller and delivery region at similar times. A different product variant or a price change between runs can look like an extraction error. Save source references with the accepted records so you can investigate those differences.
Keep the existing pipeline available during the pilot. Move a bounded set of targets after the candidate meets the output requirement, and record the migration hours instead of estimating them from memory. A full move is easier to justify when the trial shows both useful data and a cost you can explain.
What belongs in the business case
Present the recurring budget, migration cost, required output and sensitivity range together. Include the measured assumptions and the ones that still need verification. If the financial case depends on a revenue increase, identify the evidence linking that revenue to the new data rather than treating every downstream gain as an extraction benefit.
Replace the calculator's inputs with one billing period of your own data, then rerun the sensitivity check with the pilot's observed maintenance and rejection rates. Those figures are the basis for the migration decision.