


TL;DR
- Use separate API keys to identify applications and rotate credentials independently.
- Keys belonging to the same ScrapeGraphAI user share the applicable account limits. Adding keys does not multiply throughput or create separate credit balances.
- Give each key an owner, store it as a secret and validate a replacement before revoking the old key.
Separate API keys make it easier to identify a workload and replace its credentials. They do not automatically increase throughput, create a separate credit balance or isolate a production queue.
For ScrapeGraphAI, the current API implementation applies request limits by user and request category, and concurrent-job limits by user and service. Several keys belonging to the same user therefore share those limits. Plan capacity should be chosen for the combined workload, not calculated by multiplying a limit by the number of keys.
This guide explains how to organize keys, separate application workloads and plan a rotation. See the pricing page for plan allowances.
Give each credential a clear owner
A key named test can remain in use long after the test is forgotten. Name credentials for the integration that holds them and keep an inventory outside the secret itself.
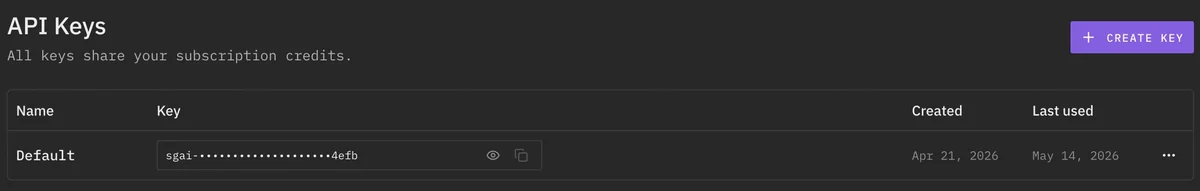 The API Keys panel displays a key’s name and usage dates while keeping its value masked. From our API-key setup walkthrough.
| Inventory field | Example | Why it matters |
|---|---|---|
| Workload | Daily product catalog refresh | Identifies what stops if the key is revoked |
| Environment | Production | Separates deployment instructions from development |
| Owner | Data platform team | Gives rotation and incident work a destination |
| Secret reference | Catalog service credential | Points to the secret store without copying the value |
| Consumers | Scheduler and catalog worker | Prevents an overlooked process from retaining an old key |
| Replacement procedure | Deploy new reference, verify, revoke old key | Makes maintenance repeatable |
| Last verification | Date and successful job identifier | Records evidence that the current configuration works |
These are recommended inventory fields, not a claim that the dashboard implements a policy for every field. Do not store the raw key in a spreadsheet, issue or notebook output.
One credential per workload can be useful when workloads have different owners or release schedules. A separate key for every individual request usually creates bookkeeping without a useful boundary.
Separate keys do not separate every resource
Consider two jobs owned by the same account: a scheduled catalog refresh and an experimental crawl. Different keys let you change their credentials independently. They still compete for shared account capacity unless a documented product boundary says otherwise.
There are several resources to distinguish:
- Authentication: which credential made the request and whether it remains valid.
- Request allowance: how many requests the account may start in the applicable interval.
- Concurrent jobs: how many crawl or monitor jobs can remain active.
- Credits: the balance that pays for operations.
- Your own infrastructure: worker slots, database capacity and downstream API limits.
Splitting credentials addresses the first item. Queue policy and workload budgeting address the others. A new key should never be treated as an instruction to multiply the allowed traffic.
For an illustrative account allowance of 100 work requests per minute, allocating 70 to catalog work and 30 to experiments is an application policy within a shared ceiling. Creating two keys does not turn that hypothetical ceiling into 200. Leave room for retries and operational requests when choosing the allocation.
Use separate queues for different deadlines
A priority job should not sit behind a large experimental backlog simply because both workers have valid credentials. Give workloads independent queues and control how much shared capacity each queue may consume.
For example, a daily catalog update might need to finish before the morning reporting job. A research crawl may tolerate several hours of delay. Start the catalog queue first or reserve worker capacity for it. Pause experiments when the deadline is at risk.
Measure queue age, accepted requests, rejected requests and completed useful records. If the queue grows while requests remain below the account limit, the bottleneck may be page latency, worker concurrency or validation. If requests are being limited, adding workers can make the backlog noisier without finishing it faster.
Use the common errors guide to separate failed retrieval, failed extraction and rejected records. Those stages require different repairs.
Rotate a key with a small verification step
A routine rotation should make the replacement observable before the previous key disappears:
- Identify every consumer of the old credential, including scheduled jobs and notebooks.
- Create the replacement through the account's supported key-management flow.
- Store it in the workload's secret store and update the deployment reference.
- Run one bounded request and a representative job through the new configuration.
- Confirm that the intended workers use the new credential, then revoke the old one.
- Verify that the old credential no longer works and record the rotation date.
For a known leak, containment may require immediate revocation rather than an overlap period. Decide that response from the actual exposure and workload, not from a promised “five-minute recovery” figure.
Avoid printing headers while debugging. A useful log can contain the workload name, provider request ID, operation, outcome and timing. It does not need the authorization value. Where a provider exposes a non-secret key identifier, use that identifier instead of a key substring.
Attribute consumption in the application
Key separation can support attribution, but it does not create complete cost accounting on its own. Record which job requested an operation and the observed usage information returned by the service.
Keep operational units separate. A crawl startup, a fetched page, an extraction and a screenshot may consume different amounts. Counting only HTTP requests can hide the cost of a large crawl or multiple outputs.
A useful daily report groups by workload and environment, then shows successful records, rejected records, consumed credits where available and spend against the chosen budget. If exact usage is unavailable for an operation, label the estimate rather than allocating an invented amount.
Use small application-level budgets for experiments. Check the budget before starting a batch, cap its size and reserve enough allowance for already running work. An alert after the balance is exhausted does not protect the scheduled production job.
The scraping economics calculator adds engineering and review time to infrastructure costs. It helps distinguish a more expensive API plan from a more expensive overall workflow.
Decide whether the account needs more capacity
A plan change is justified by measured demand, not by the number of credentials. Gather the busiest interval, the required completion deadline, service latency, active-job count and budget consumption.
If the bottleneck is a shared request allowance, evaluate the documented plan limits. If jobs are mostly waiting on unavailable sources, a larger allowance may only start more failing requests. If validation rejects many records, repair the source selection or schema before increasing collection volume.
Maintain a small runbook with the current owners, secret references, queue priorities, budget rules and rotation procedure. Test it when a new integration is added. A separate catalog-worker key is useful when you can replace it without redeploying unrelated integrations. The inventory tells you which workers need the new value; the queue and budget controls determine whether their jobs finish on time.