


TL;DR
- Fetch a public Facebook Page with Python Requests, read its Open Graph metadata and extract the labeled metrics into JSON with ScrapeGraphAI.
- Validate Page identity and compare extracted values with the fetched source. Keep Page likes, followers and talking-about counts separate; missing values stay null.
- This tutorial covers public Page metadata. It does not collect posts, comments, private profiles or follower lists.

Run the example in Google Colab with your own ScrapeGraphAI API key.
This Facebook scraper reads the public metadata of a Page, extracts the metrics explicitly stated there and exports a validated JSON record. It starts with a live HTTP request. You do not need to paste a saved example into the notebook.
The example uses Meta's public Page. Python Requests obtains its HTML, Beautiful Soup reads the Page title and description, and ScrapeGraphAI interprets the description with a schema. Local checks compare the extracted values with the same source before anything is written as an accepted record.
This is a Page-metadata workflow. It does not collect posts, comments, private profiles or a complete follower list. Public metadata can be much smaller than the Page visible in a browser, so the exported record says exactly which source was used.
What the source can tell you
Anonymous requests to https://www.facebook.com/Meta returned Page-specific Open Graph metadata locally and in a Google Colab runtime. The local response used Italian labels for Page likes and people talking about the Page; Colab returned English labels. The logged-in interface displayed a rounded follower count elsewhere. Those are different observations and must stay separate.
The code retains the displayed metric strings. A value such as 1.2K stays 1.2K; the application does not invent an exact count. A missing follower metric stays null even when the description includes a large likes count.
| Field | Source and meaning |
|---|---|
page_name |
Exact og:title from the fetched Page |
likes_display |
Number explicitly labeled as Page likes |
followers_display |
Number explicitly labeled as followers, if present |
talking_about_display |
Separately labeled talking-about value, if present |
description |
Original og:description, kept for review |
observed_at |
Time the HTTP response was obtained |
Use an approved collection method for your intended use. Meta's scraping explanation distinguishes authorized collection from automation that violates its terms. A successful public HTTP response does not settle permission or reuse rights. This example sends no Facebook cookies, account credentials or private browser content to another service.
Install the tested packages
Use Python 3.12 or newer. The complete notebook makes one public Facebook HTTP request and two ScrapeGraphAI Extract calls, including a missing-data fixture. The Extract calls use your service credits. It requests the API key through a hidden prompt unless you already set SGAI_API_KEY.
import subprocess
import sys

if sys.version_info < (3, 12):
    raise RuntimeError("Use Python 3.12 or newer.")
subprocess.check_call([
    sys.executable, "-m", "pip", "install", "--quiet",
    "requests==2.34.2", "beautifulsoup4==4.14.3",
    "scrapegraph-py==2.3.1", "jsonschema==4.26.0",
])
Fetch the Page and verify its identity
An HTTP 200 response alone is insufficient. A login screen can also return 200. This example requires a Page-specific title, a description and the expected canonical Page URL before calling the extractor.
Change both url and expected_name when adapting it to another public Page. The URL comparison accepts a trailing slash but rejects a redirect to a different path. If the required metadata is unavailable, the cell stops; it never substitutes the old sample or an empty successful record.
from datetime import datetime, timezone
from hashlib import sha256
from urllib.parse import urlsplit
import json
import requests
from bs4 import BeautifulSoup

url = "https://www.facebook.com/Meta"
expected_name = "Meta"

def page_identity(value):
    parsed = urlsplit(value)
    if parsed.scheme != "https" or parsed.hostname not in ("facebook.com", "www.facebook.com"):
        raise ValueError("Expected an HTTPS Facebook Page URL.")
    return parsed.path.rstrip("/").casefold(), parsed.query

response = requests.get(url, timeout=30)
response.raise_for_status()
observed_at = datetime.now(timezone.utc).isoformat()
if "text/html" not in response.headers.get("Content-Type", "").lower():
    raise ValueError("The response is not HTML.")
if page_identity(response.url) != page_identity(url):
    raise ValueError("The request did not reach the expected Page.")
soup = BeautifulSoup(response.text, "html.parser")
metadata = {
    tag.get("property"): tag.get("content", "").strip()
    for tag in soup.select("meta[property]")
    if tag.get("property") in ("og:title", "og:description", "og:url")
}
if metadata.get("og:title") != expected_name or not metadata.get("og:description"):
    raise ValueError("Page metadata is missing or does not match the expected name.")
if page_identity(metadata.get("og:url", "")) != page_identity(url):
    raise ValueError("The metadata describes a different Page.")
snapshot = {
    "source_url": url,
    "observed_at": observed_at,
    "acquisition_method": "anonymous HTTP request; selected Open Graph metadata",
    "page_name": metadata["og:title"],
    "description": metadata["og:description"],
}
source_text = json.dumps(metadata, ensure_ascii=False, sort_keys=True)
snapshot["content_sha256"] = sha256(source_text.encode("utf-8")).hexdigest()
print(snapshot)Only the selected public metadata goes into source_text. The notebook does not persist the full HTML, tracking URLs or images. The hash identifies the selected input; it is not a digital signature from Facebook.
Extract the labeled metrics
ScrapeGraphAI Extract accepts supplied content, which lets this call interpret the HTML metadata already obtained by Requests. It does not repeat the Facebook fetch or inherit a browser session.
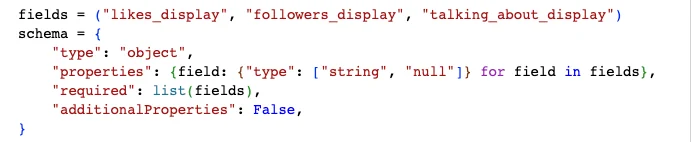 The Colab notebook keeps likes, followers and talking-about counts in separate fields and allows missing values.
The prompt distinguishes likes, followers and talking-about values. It asks for literal numeric labels, including their separators or abbreviations, and nulls for anything absent. For one stable description format, a deterministic parser may be enough; this example uses extraction plus an independent parser to demonstrate how to check an AI result.
import os
from getpass import getpass
from jsonschema import validate
from scrapegraph_py import ScrapeGraphAI

fields = ("likes_display", "followers_display", "talking_about_display")
schema = {
    "type": "object",
    "properties": {field: {"type": ["string", "null"]} for field in fields},
    "required": list(fields),
    "additionalProperties": False,
}
prompt = (
    "Read only the supplied Page description. Extract the numeric display for "
    "Page likes, followers, and people talking about the Page. These are separate "
    "metrics: never use likes as followers. Italian 'Mi piace: NUMBER' means "
    "Page likes; 'NUMBER persone ne parlano' means talking about. Copy each "
    "numeric display verbatim, preserving punctuation, spaces within the number "
    "and suffixes such as K or M. Exclude surrounding words. Use null if the "
    "description does not explicitly state a metric. Do not infer values."
)
with ScrapeGraphAI(
    api_key=os.environ.get("SGAI_API_KEY") or getpass("ScrapeGraphAI API key: ")
) as client:
    result = client.extract(prompt, markdown=snapshot["description"], schema=schema)
    if result.status != "success" or result.data is None:
        raise RuntimeError(f"Extraction failed: {result.error}")
    metrics = result.data.json_data
    validate(instance=metrics, schema=schema)
    fixture = client.extract(
        prompt, markdown="Example Workshop. Handmade furniture and repairs.", schema=schema
    )
    if fixture.status != "success" or fixture.data is None:
        raise RuntimeError(f"Fixture extraction failed: {fixture.error}")
    missing = fixture.data.json_data
    validate(instance=missing, schema=schema)
    assert missing == dict.fromkeys(fields), missing
print(metrics)
The second call is an explicit synthetic fixture. It checks that the model leaves all three fields null when the description contains no audience metrics. Its output is never substituted for the live Page record.
Compare with the source before accepting the result
The reference parser below covers the English and Italian label patterns used in the tests. It does not claim to support every language Facebook may return. If extraction finds a metric that this reference parser cannot recognize, the comparison fails and you must review the description before extending the parser.
import re

number = r"(\d[\d.,]*(?:\s?[KMB])?)"
patterns = {
    "likes_display": [rf"{number}\s+likes\b", rf"Mi piace:\s*{number}"],
    "followers_display": [rf"{number}\s+followers\b", rf"{number}\s+follower\b"],
    "talking_about_display": [
        rf"{number}\s+(?:people\s+)?talking about",
        rf"{number}\s+persone ne parlano",
    ],
}

def reference_metrics(description):
    values = {}
    for field, variants in patterns.items():
        matches = {
            match.group(1).strip()
            for pattern in variants
            for match in re.finditer(pattern, description, re.IGNORECASE)
        }
        if len(matches) > 1:
            raise ValueError(f"Ambiguous values for {field}.")
        values[field] = next(iter(matches), None)
    return values

reference = reference_metrics(snapshot["description"])
if metrics != reference:
    raise ValueError(f"Extraction differs from the source check: {metrics} / {reference}")
assert reference_metrics("Example. 1.2K followers.") == {
    "likes_display": None, "followers_display": "1.2K", "talking_about_display": None
}
assert reference_metrics("Example. Mi piace: 1.234 · 25 persone ne parlano.") == {
    "likes_display": "1.234", "followers_display": None, "talking_about_display": "25"
}
assert reference_metrics("Example. 1,234 likes · 25 talking about this.") == {
    "likes_display": "1,234", "followers_display": None, "talking_about_display": "25"
}
print("Source comparison and missing-data checks passed.")
These checks verify this input and the listed fixtures. They do not establish a platform-wide extraction accuracy rate. Inspect the source text when a new locale or label appears, and keep the failed observation separate from accepted records.
Export JSON with provenance
The exported record includes the original description so that another person can review the values. Observation time belongs to the fetch; processing time belongs to the extraction and export. Keeping both prevents an old input from appearing freshly observed merely because you reran a later cell.
from pathlib import Path

record = {
    **snapshot,
    "processed_at": datetime.now(timezone.utc).isoformat(),
    "metrics": metrics,
}
output = Path("facebook-page-record.json")
output.write_text(json.dumps(record, indent=2, ensure_ascii=False), encoding="utf-8")
assert json.loads(output.read_text(encoding="utf-8")) == record
print(json.dumps(record, indent=2, ensure_ascii=False))
A successful run writes facebook-page-record.json. The local response contained a Page-likes value and a talking-about value, with followers_display null. Counts and language can change between runs; the checks use the fetched description rather than hard-coded current counts.
Compare repeat observations carefully
This final cell tests change detection with a synthetic previous record. It reports changes to literal displays, not exact audience growth. A locale change or a formatting change may alter a display without altering its underlying count.
from copy import deepcopy

def changed_displays(previous, current):
    if previous["source_url"] != current["source_url"]:
        raise ValueError("Compare observations of the same Page.")
    return {
        field: {"previous": previous["metrics"][field], "current": current["metrics"][field]}
        for field in fields
        if previous["metrics"][field] != current["metrics"][field]
    }

synthetic_previous = deepcopy(record)
synthetic_previous["metrics"]["likes_display"] = "synthetic previous display"
changes = changed_displays(synthetic_previous, record)
assert set(changes) == {"likes_display"}
assert changed_displays(record, record) == {}
print({"fixture": "synthetic previous record", "display_changes": changes})
For recurring collection, rerun the fetch and all validation stages before storing an observation. Keep failures visible, retain the previous accepted record and review a null transition before treating it as a Page change. The common errors guide explains how to separate access failures from extraction and storage errors.
Apply the workflow to another public Page
Set url to the public Page you want to inspect and expected_name to its Page name, then run the notebook from the fetch cell onward. The workflow reads the Page metadata with Python Requests, extracts the labeled metrics with ScrapeGraphAI and writes the checked record to JSON.
Review the returned description and retain its language and numeric formatting. Keep the source URL and observation time with each export so repeat observations can be compared using the same Page identity and metric labels.
For Page-management data beyond this public metadata, evaluate Meta's approved interfaces and validate the fields your application needs.